About me
Hi! I am a Machine Learning Engineer at Hyperscience in New York, working on a document AI platform built on proprietary as well as fine-tuned open-source models. Among other things, I work on Vision Language Models: making self-hosted inference cheaper and faster, building the pipelines that train and evaluate them, and holding automated predictions to the accuracy targets our customers set.
I am originally from France, where I earned a master’s degree in Applied Mathematics at École Polytechnique, before completing the MS in Data Science at Columbia University. Along the way, I interned in RL research at Huawei in London, training a deep generative model to imitate “expert-like” navigation on different types of surfaces, and joined Hyperscience as a research intern to reconstruct reading order on documents with complex layouts. I also served as a teaching assistant in electromagnetism and thermodynamics at Shanghai Jiao Tong University for two consecutive semesters.
Portfolio
The projects below are older work from my school years.
Image-to-image translation with cGAN
Performed image colorization and reconstruction with pix2pix[1]-like cGAN architecture
- Implemented U-Net generator and discriminator and conducted ablation experiments on reconstruction task for Facades dataset
- Pretrained downsampling path of generator on ImageNet and finetuned whole generator on Country211 dataset for colorization task
[1] Philip Isola and Jun-Yan Zhu, Tinghui Zhou and Alexei A. Efros, Image-to-Image Translation with Conditional Adversarial Networks, arvix: https://arxiv.org/abs/1611.07004, doi: 10.48550/ARXIV.1611.07004.

Surgical phase recognition
Developing phase recognition models based on MobileNetV2 [1] to classify frames from Hernia surgery videos (14 labels)
- Used MobileNetV2 as backbone to design and implement four different phase recognition architectures :
- MobileNet : backbone to extract features + simple linear layer
- MobileNetStage : added linear treatment of [frame idx / # frames in video] to model correlation between time and label
- MobileNetLSTM : added LSTM to model correlation between labels of consecutive frames (padded when necessary)
- MobileNetFC : channelized backbone features from consecutive frames + linear layer (same idea as LSTM)
- Coded smoothing operation to replace noisy labels in prediction
- Achieved 80.0% accuracy and 0.55 macro F1-score on test data
[1] Sandler, Mark, et al. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” ArXiv:1801.04381 [Cs], Mar. 2019. arXiv.org, http://arxiv.org/abs/1801.04381.

GitHub
Breast Histopathology : custom ResNet
Predicting whether a breast tissue patch (scanned at x40) is cancerous
- Built customized versions of ResNet18, ResNet34 and ResNet50 [1] in PyTorch to cope with the low dimensionality of the images : 50x50x3 vs. 224x224x3 for ImageNet [2]
- Trained models to detect cancerous patches and achieved 85.8% test accuracy (81.4% for Gradient Boosting)
[1] Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun. Deep Residual Learning for Image Recognition. arXiv:1512.03385
[2] Deng, J. et al., 2009. Imagenet: A large-scale hierarchical image database. In 2009 IEEE conference on computer vision and pattern recognition. pp. 248–255
Squeeze and Excitation Networks
Performing adaptative channel-wise feature recalibration to enhance state-of-the-art CNN architectures
- Implemented ResNet [1], ResNeXt [2] and InceptionV3 [3] in TensorFlow as well as Squeeze and Excitation blocks [4]
- Reduced classification error using correlation modules on CIFAR-10 [5], CIFAR-100 [6] and Tiny ImageNet [7] by 0.5 to 4.5% for ResNet and ResNeXt
- Performed analysis of ratio, stage integration, activation distributions and inference time with SE blocks
[1] Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun. Deep Residual Learning for Image Recognition. arXiv:1512.03385
[2] S. Hitawala, Evaluating ResNeXt Model Architecture for Image Classification, CoRR. abs/1805.08700 (2018)
[3] Christian Szegedy, Vincent Vanhoucke, Sergey Ioffe, Jonathon Shlens, Zbigniew Wojna, “Rethinking the Inception Architecture for Computer Vision”, arXiv [cs.CV] 2015
[4] Hu, J., Shen, L., Albanie, S., Sun, G. and Wu, E., 2022. Squeeze-and-Excitation Networks
[5] Krizhevsky, Alex, Vinod Nair, and Geoffrey Hinton. ”The CIFAR-10 dataset.” online: http://www.cs.toronto.edu/kriz/cifar. html (2014)
[6] Krizhevsky, Alex, Vinod Nair, and Geoffrey Hinton. ”The CIFAR-100 dataset.” online: http://www.cs.toronto.edu/kriz/cifar. html (2014)
[7] Jiayu Wu, Qixiang Zhang, and Guoxi Xu. Tiny imageNet challenge. Technical Report, 2017
Energy consumption and human development
Puting to the test some intuitive insights between energy consumption and human development core components
- Conducted analysis of the cross directional causality between energy consumption, GDP, years of schooling and life expectancy
- Built an interactive component to visualize the evolution of the energy mix across time for various HDI index ranges (D3)
GitHub
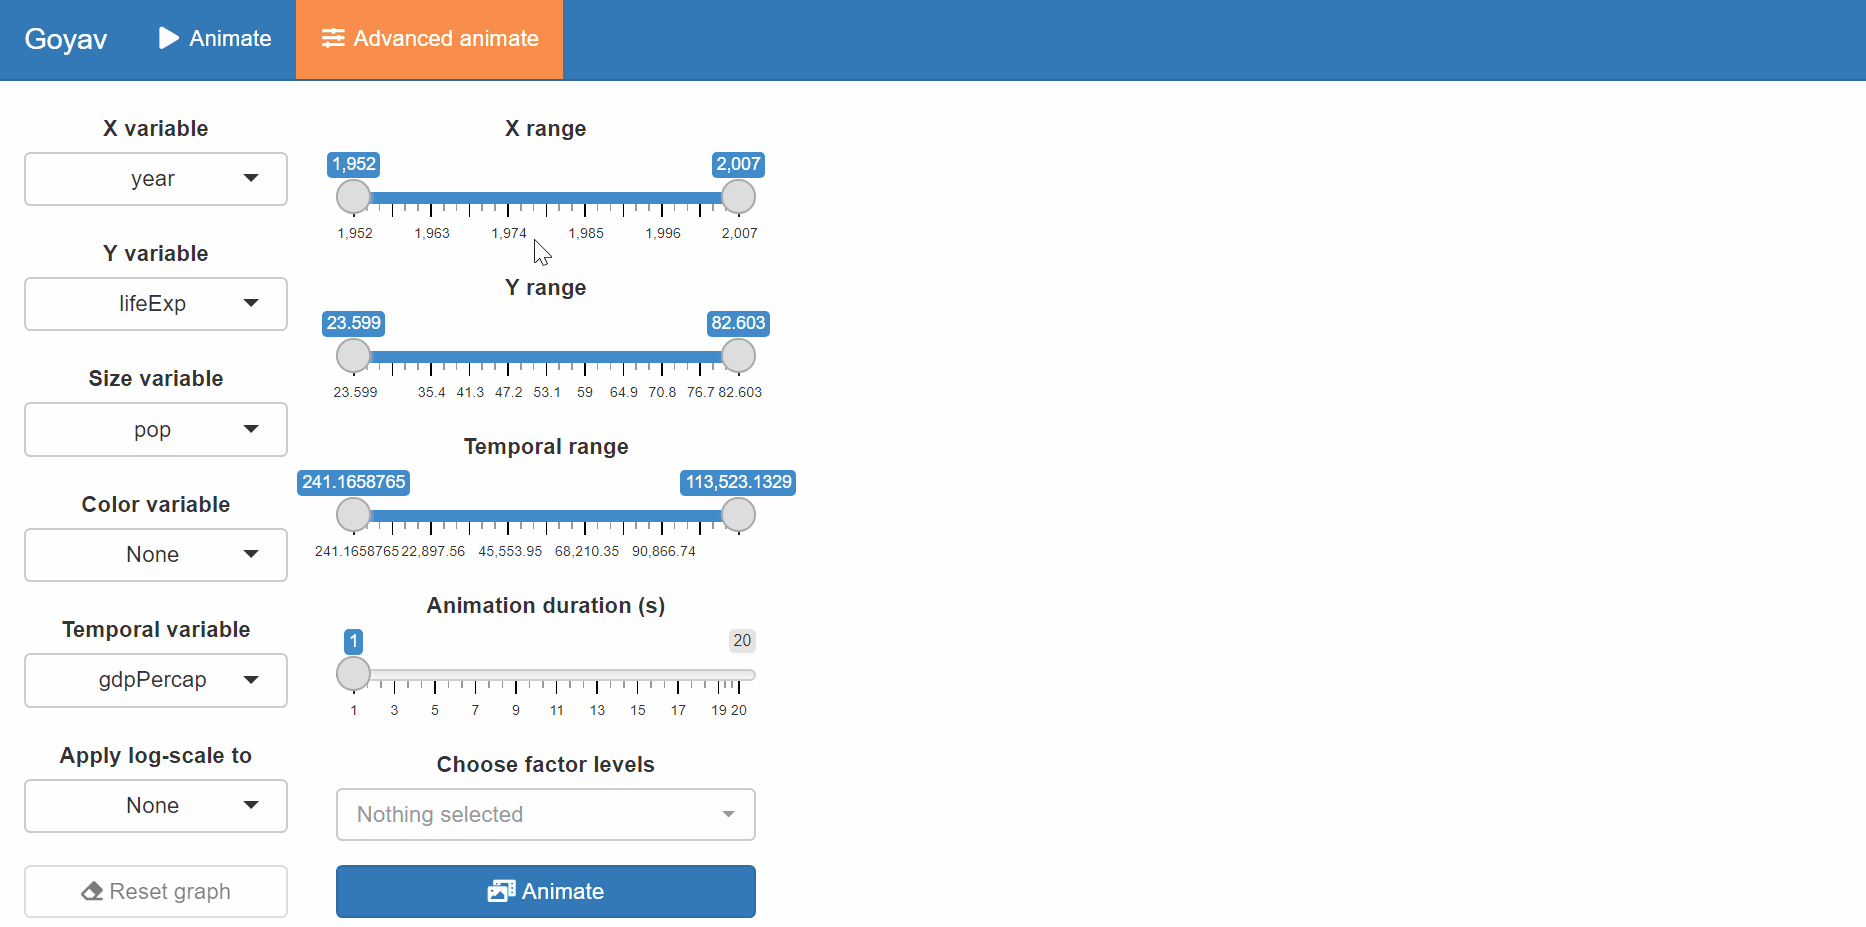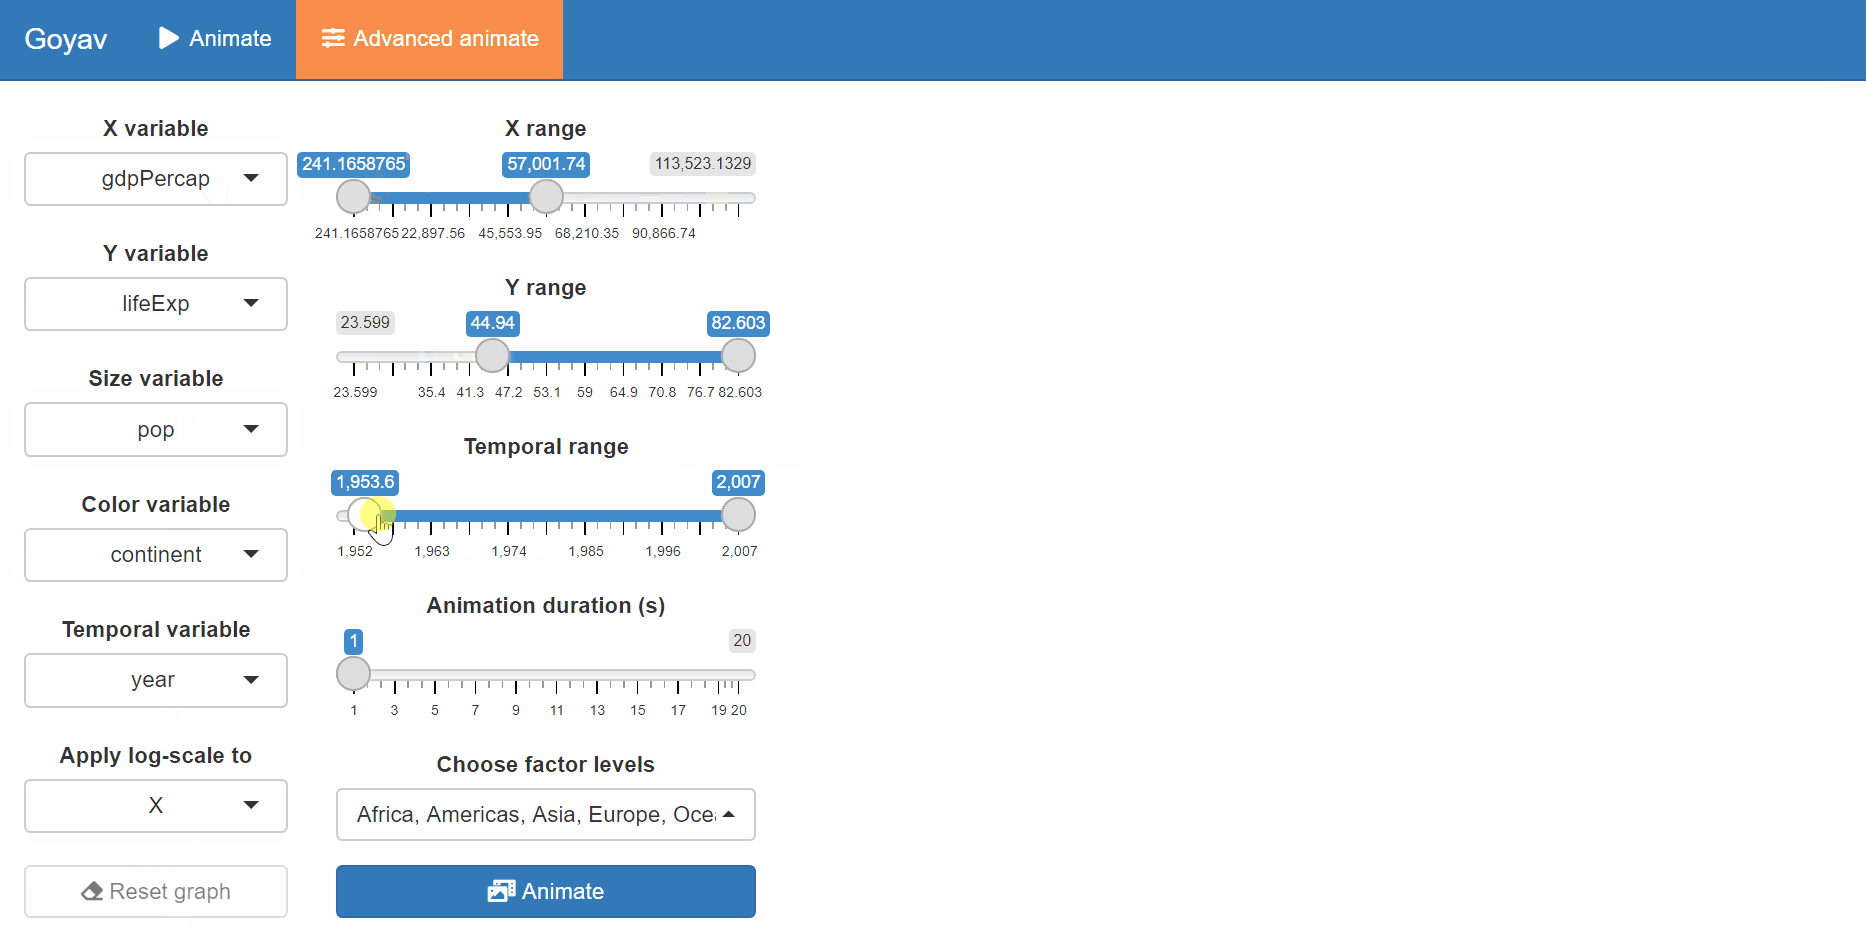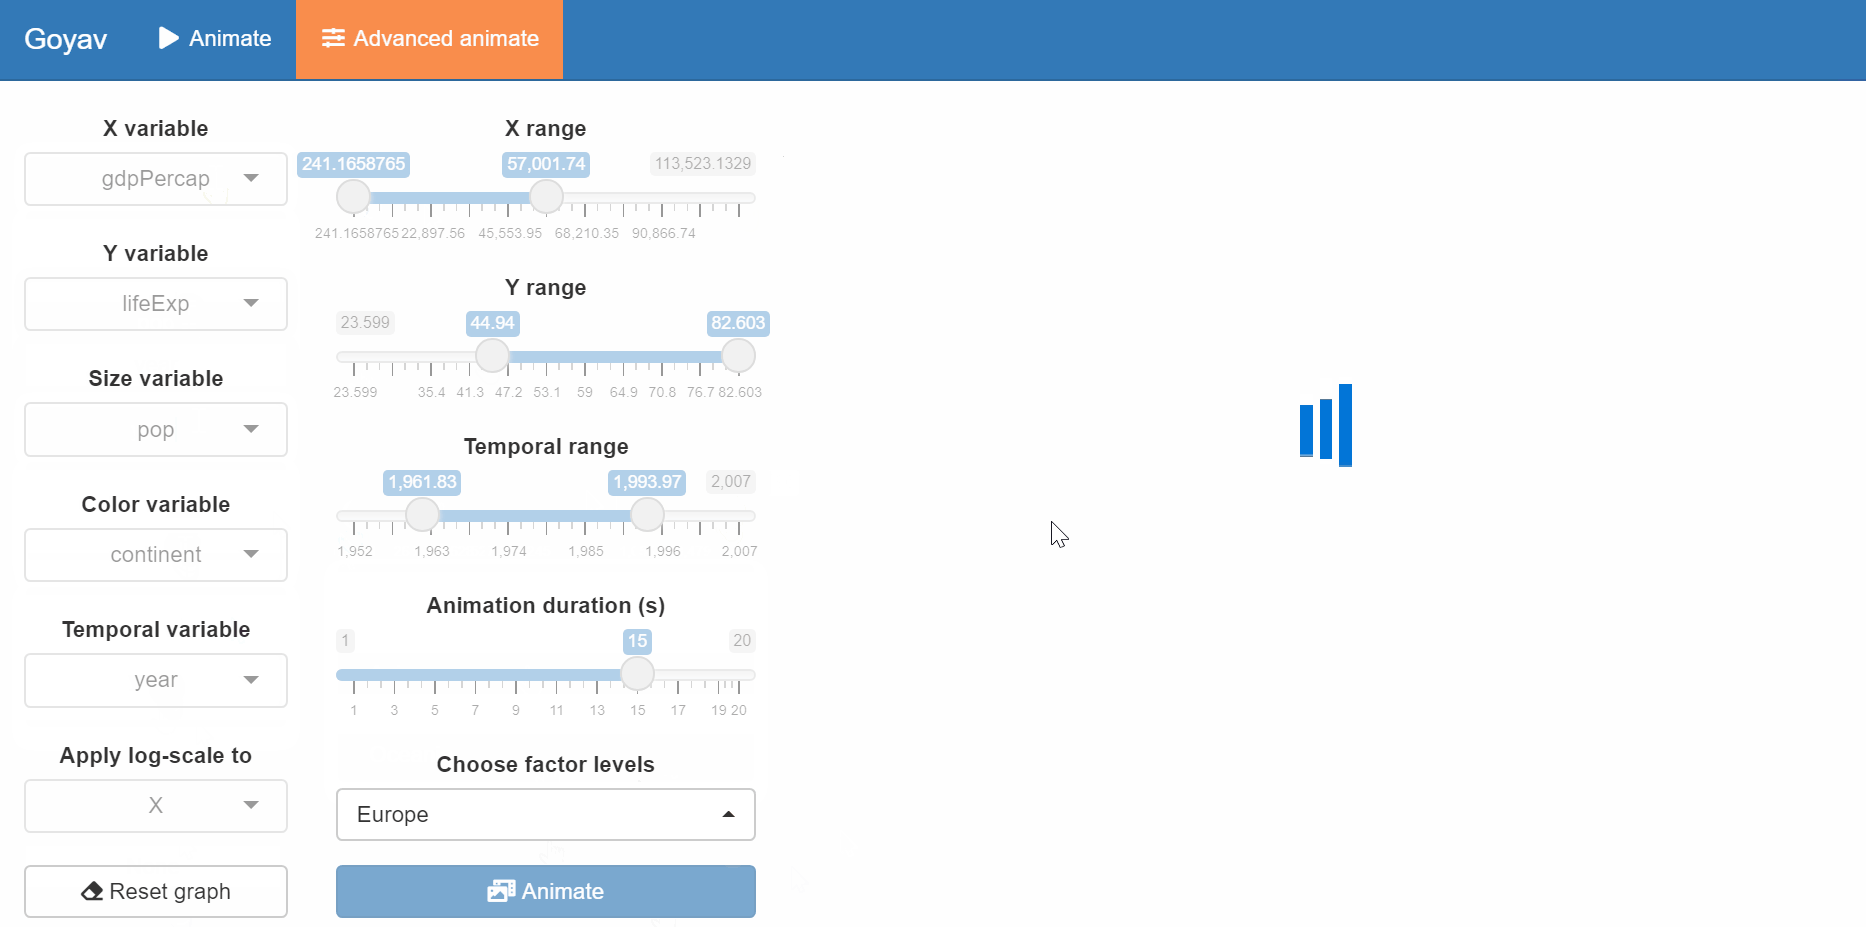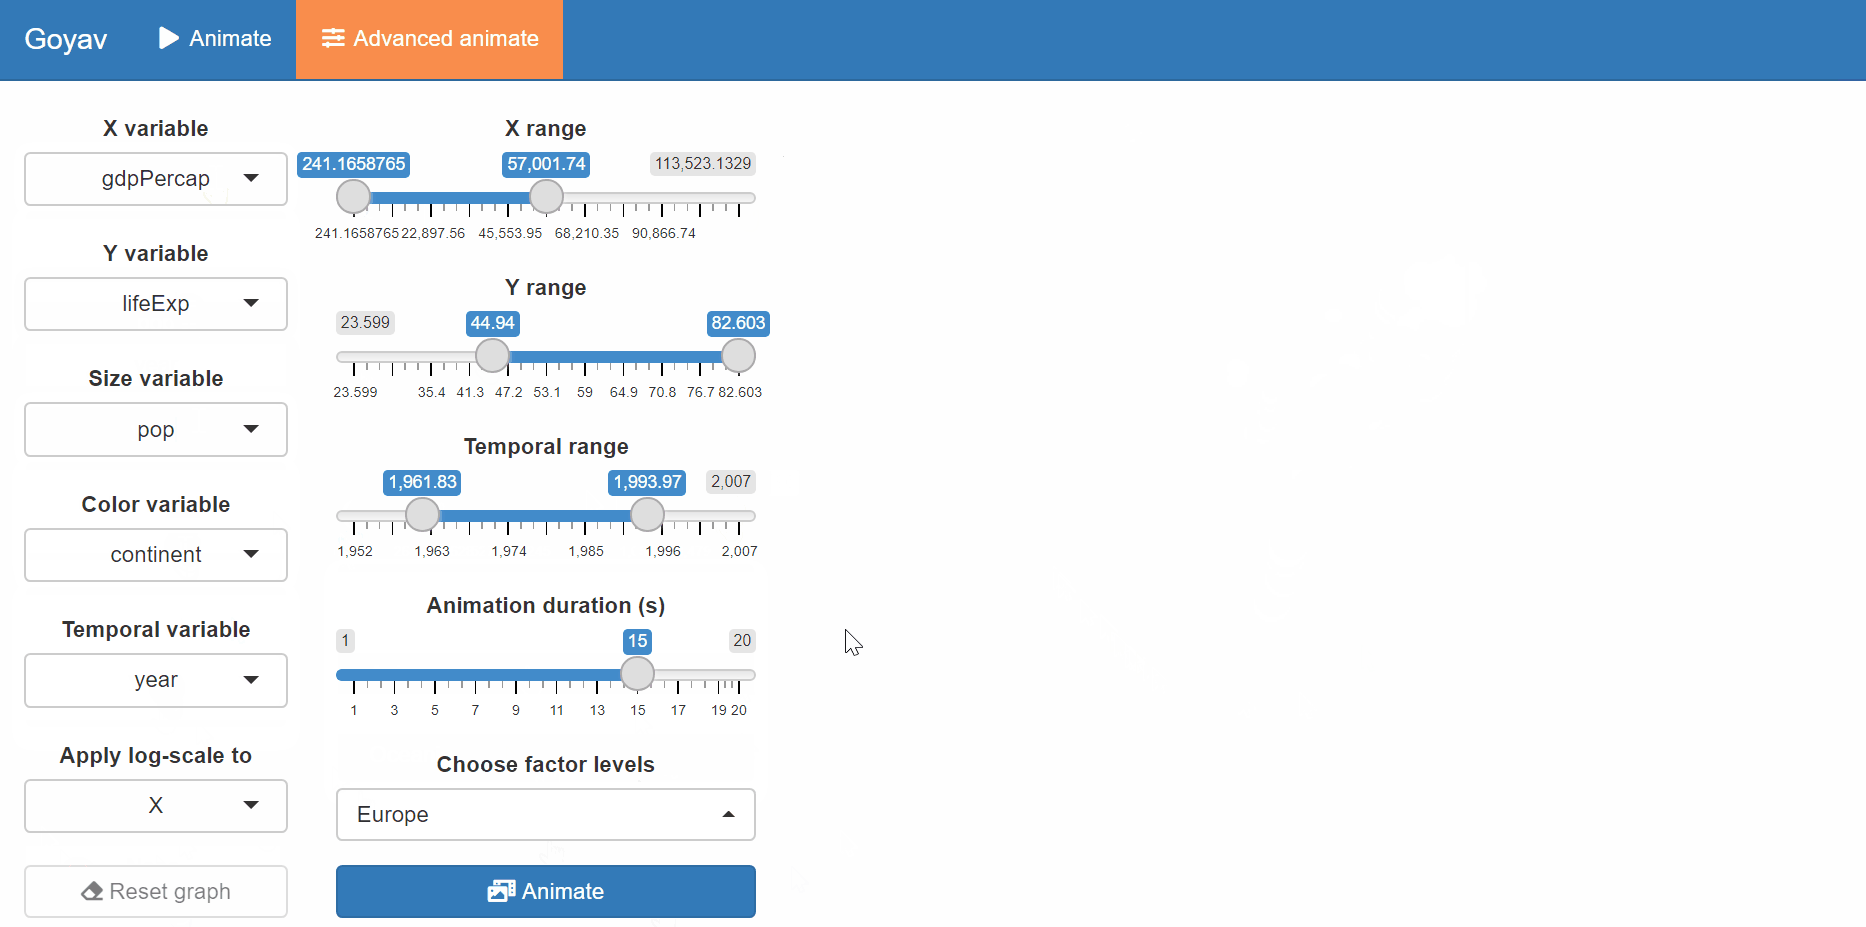
Goyav
Creating an R package to easily animate data
- Developed a Shiny App meant to create highly customizable animated gifs from a dynamic interface
Breast Histopathology : exploratory analysis and classification with scikit-learn
Predicting whether a breast tissue patch (scanned at x40) is cancerous
- Conducted exploratory data analysis of patches (e.g., class balance, kernel density of tissue color in HSV space)
- Oversampled cancerous patches and selected XGBoost as best classifier based on cross-validation (81.4% best test acc.)
Integration of physical models into voxel-based video games
Teaching gamers how classical mechanics, thermodynamics and chemistry interact together and how to improve their gameplay accordingly
- Implemented thermal model of corrosion, diffusion, and passivation of metallic voxel on Unity engine in C#
- Built gameplay to interact with these models in order to enhance pedagogical and recreational features of the game
GitHub
Predicting how many times a tweet will be retweeted
- Carried out thematic clustering and differential prediction of #retweets with Gradient Boosting and Quantile regression
- Performed text embedding with Bidirectional Encoder Representations (BERT, Google) [1] for deep prediction
[1] Devlin, J., Chang, M., Lee, K. and Toutanova, K., 2022. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding